

Ordinal vs Multinomial Logistic Regression (2026): Which One Does Your Categorical Outcome Need?
Your outcome variable has more than two categories, so binary logistic regression is out. The remaining choice is between two models, and it turns on a single question: do the categories have a natural order?
If they do — low, medium, high; disagree, neutral, agree; first, upper second, lower second — ordinal logistic regression is the more powerful choice, because it uses the ordering as information. If they do not — which of four transport modes, which of five degree subjects, which of three treatment routes — multinomial logistic regression is the only valid option.
The complication is that ordinal regression buys its extra power with an assumption most students never test, and when that assumption fails the correct answer is usually to run the multinomial model instead. This guide covers the comparison, the assumption test, what to do when it fails, and how to report either model.
The comparison at a glance
| Ordinal logistic regression | Multinomial logistic regression | |
|---|---|---|
| Outcome | 3+ ordered categories | 3+ unordered categories |
| What it models | The odds of being at or below each category boundary | The odds of each category against one reference category |
| Coefficients estimated | One set for all boundaries | A separate set for every category but the reference |
| Key assumption | Proportional odds (parallel lines) | Independence of irrelevant alternatives |
| Statistical power | Higher — uses the ordering | Lower — discards the ordering |
| Sample size needed | Smaller | Larger, and it grows with the number of categories |
| Effect reported as | Cumulative odds ratio | Relative risk ratio per category |
| SPSS menu | Analyze > Regression > Ordinal | Analyze > Regression > Multinomial Logistic |
| Interpretive difficulty | One coefficient per predictor | Several coefficients per predictor |
Step 1: Establish whether your categories are genuinely ordered
Order means that moving from one category to the next always goes the same direction on a single underlying dimension. Satisfaction ratings are ordered. Degree classifications are ordered. Stages of a condition are ordered.
Subject of study is not ordered. Neither is employment sector, preferred platform, or reason for dropping out. If you cannot state what the categories are increasing in, they are nominal, and the choice is made for you.
The trap sits between the two. Categories such as “employed, studying, unemployed” look like they might be ordered because they are often listed in a fixed sequence, but a sequence in your codebook is not an order in the world. If you cannot defend the ordering to an examiner in one sentence, treat the outcome as nominal.
Before either model, satisfy yourself that the outcome could not simply be continuous. If you created these categories by cutting a continuous measure into bands, undo it. Banding throws away information and reduces power for nothing — the point the guide to linear versus logistic regression makes about dichotomising applies with equal force to three-way splits.
Step 2: Run the ordinal model and test proportional odds
Proportional odds is the assumption that gives ordinal regression its efficiency: it holds that each predictor has the same effect at every category boundary. If income predicts moving from “low” to “medium” satisfaction just as strongly as it predicts moving from “medium” to “high”, the assumption holds and one coefficient can stand for both transitions.
In SPSS, go to Analyze > Regression > Ordinal, put your outcome in Dependent, categorical predictors in Factor(s) and continuous predictors in Covariate(s). Under Output, tick Test of parallel lines. That checkbox is the assumption test, and it is the single most-skipped step in the whole procedure.
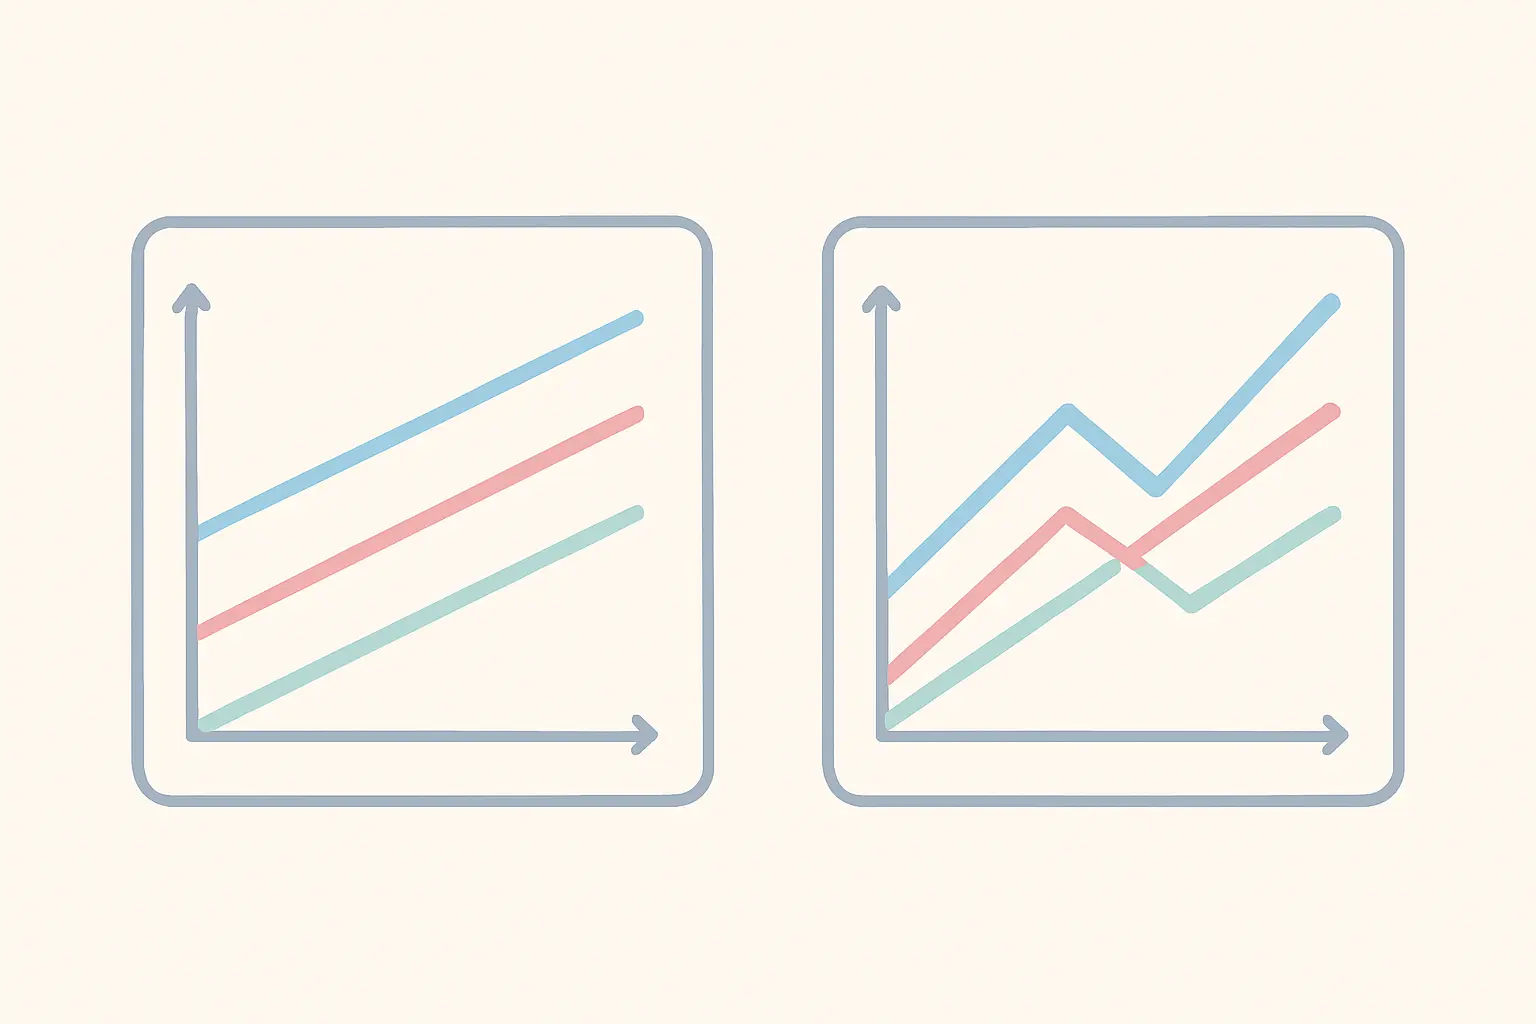
Read the test backwards from the usual habit. A non-significant result means the assumption holds and the ordinal model is appropriate. A significant result means at least one predictor behaves differently at different thresholds, and the single set of coefficients is misrepresenting your data.
Two cautions. The test is sensitive: with a large sample it can flag departures too small to change any conclusion, so inspect the size of the difference rather than obeying the p-value mechanically. And with continuous predictors or small cells it can be unstable, which is one reason the partial proportional odds model exists.
Step 3: What to do when parallel lines fails
You have three defensible routes, and the write-up matters as much as the choice.
Switch to multinomial. The safest and most common answer. You lose power and gain coefficients, but you stop assuming something your data have contradicted. State that the test of parallel lines was significant and that the model was changed as a result.
Fit a partial proportional odds model. This relaxes the assumption for only the predictors that violate it and keeps it for the rest. It is not available in the standard SPSS ordinal dialog — it needs the gologit2 command in Stata, or the VGAM or ordinal packages in R. Worth the effort if the ordering is central to your argument.
Collapse categories. Sometimes a five-point outcome with two nearly empty categories violates the assumption simply because those cells are too thin. Merging adjacent categories can resolve it, but only where the merge is substantively meaningful. Collapsing to make an assumption pass is a decision you must declare and justify, not a technical tidy-up.
Whichever route you take, report the original test result. A reader who sees only the final model cannot tell whether the assumption was checked.
Step 4: Run the multinomial model
Go to Analyze > Regression > Multinomial Logistic. The critical extra decision here is the reference category, because every coefficient is expressed relative to it.
Choose the reference on substantive grounds — the status quo, the largest group, the comparison your research question implies — and never leave it on the default without checking what the default is. Changing the reference does not change the model, but it changes every number in your table and every sentence you write about them.
Expect the output to be large. With four outcome categories and five predictors, you have three sets of five coefficients to interpret. This is the real cost of the multinomial model, and it is why the ordinal model is preferred whenever the assumption genuinely holds.
Step 5: Interpret the coefficients correctly
The two models produce numbers that look alike and mean different things.
In the ordinal model, an odds ratio is cumulative. An odds ratio of 1.45 for a predictor means that a one-unit increase multiplies the odds of being in a higher category rather than at or below the current one by 1.45 — and, because of proportional odds, by the same 1.45 at every boundary. That single number is the model’s whole appeal.
In the multinomial model, each coefficient is a relative risk ratio comparing one specific category against the reference. A value of 1.45 for category B says that a one-unit increase multiplies the relative odds of B rather than the reference by 1.45, and tells you nothing at all about category C.
Report odds ratios with their confidence intervals rather than raw log-odds coefficients, which almost nobody can interpret on sight. For model fit, use the likelihood ratio chi-square for overall significance and report a pseudo R-squared — Nagelkerke is the conventional choice — while stating plainly that it is not the proportion of variance explained that linear regression reports.
Step 6: Check you have enough data
Both models are hungrier than they look, and the multinomial is hungrier than the ordinal.
The working convention is at least ten cases in the smallest outcome category for every predictor you fit. With four predictors and a smallest category of 22 people, you are already at the edge. Empty or near-empty cells in the cross-tabulation of a categorical predictor against the outcome are the commonest cause of wild coefficients and enormous standard errors, so cross-tabulate before you model — the procedure in the chi-square walkthrough is the check you want.
Plan this before collection rather than discovering it afterwards; the power analysis guide covers how to approach it. And screen the data first: a handful of invalid responses concentrated in one small category can distort a model that a larger category would have absorbed.
The recommendation
Start ordinal whenever your categories are genuinely ordered, because it is more powerful, needs fewer participants, and produces one interpretable number per predictor instead of several. Tick Test of parallel lines at the same time, and treat the result as a real decision point rather than a formality.
If the assumption holds, report the ordinal model and say the test was passed. If it fails, move to multinomial and say why. The examiner is looking for evidence that you knew the assumption existed — not for a particular model.
For the wider map of which model any given outcome variable needs, the statistical test decision guide places both of these alongside the rest of your options.
Frequently asked questions
Can I use ordinal regression on a Likert outcome?
On a single Likert item, yes — it is exactly the right model, and more defensible than treating a five-point item as continuous. On a composite scale score built from many items, linear regression is usually the better choice. See the guide to designing a Likert scale questionnaire for the item-versus-scale distinction.
What does a significant test of parallel lines actually mean?
That at least one predictor’s effect differs across the category thresholds, so a single coefficient per predictor misdescribes your data. It is not a verdict on your whole analysis — it is a signal to change model, relax the assumption for the offending predictor, or reconsider your categories.
Can I just run multinomial regression on ordered data to be safe?
You can, and it will be valid, but it discards the ordering and costs you power. If your ordinal model passes the assumption test, using it is the stronger choice and easier to write up.
How do I choose the reference category?
On substance, not convenience. Pick the category your research question naturally compares against — the control condition, the default choice, or the largest group. State which one you used, because your coefficients are meaningless without it.
What is the independence of irrelevant alternatives?
The multinomial assumption that the relative odds between two categories do not change if a third is added or removed. It is most often violated when two of your categories are close substitutes, and the usual response is to reconsider whether those categories should be separate.
Why is my pseudo R-squared so low?
Because pseudo R-squared measures something different from the R-squared in linear regression and is routinely much smaller. Report it, name which one it is, and do not interpret it as a percentage of variance explained.
Can I run these models with a small sample?
Ordinal regression tolerates a smaller sample than multinomial, but neither is forgiving. If the smallest outcome category holds fewer than about ten cases per predictor, reduce the number of predictors or merge categories rather than reporting unstable estimates.
Do I need to check for multicollinearity?
Yes, and neither dialog reports it directly. The standard workaround is to run a linear regression with the same predictor set purely to obtain the tolerance and VIF statistics, then discard that model.
How do I report either model in APA 7?
Give the model chi-square with its degrees of freedom and p-value, a pseudo R-squared with its name, and then a table of predictors with odds ratios or relative risk ratios, confidence intervals and p-values. For the ordinal model, state the result of the test of parallel lines. For the multinomial, state the reference category in the table note. The conventions for intervals are set out in the guide to effect sizes and confidence intervals.
Writing it up
The paragraph that earns marks names the measurement level of the outcome, justifies the model from that, reports the assumption test, and interprets one or two odds ratios in plain language before referring the reader to the table.
If you are drafting that section now, Tesify can turn your output into a properly structured APA 7 results passage, with the cumulative and relative interpretations kept distinct and the reference category stated where it belongs.
Write your thesis with AI
Structure, draft, cite, and format your thesis faster with Tesify’s AI writing tools, automatic bibliography, and plagiarism checker. Free to start, no credit card required.

Leave a Reply